Description
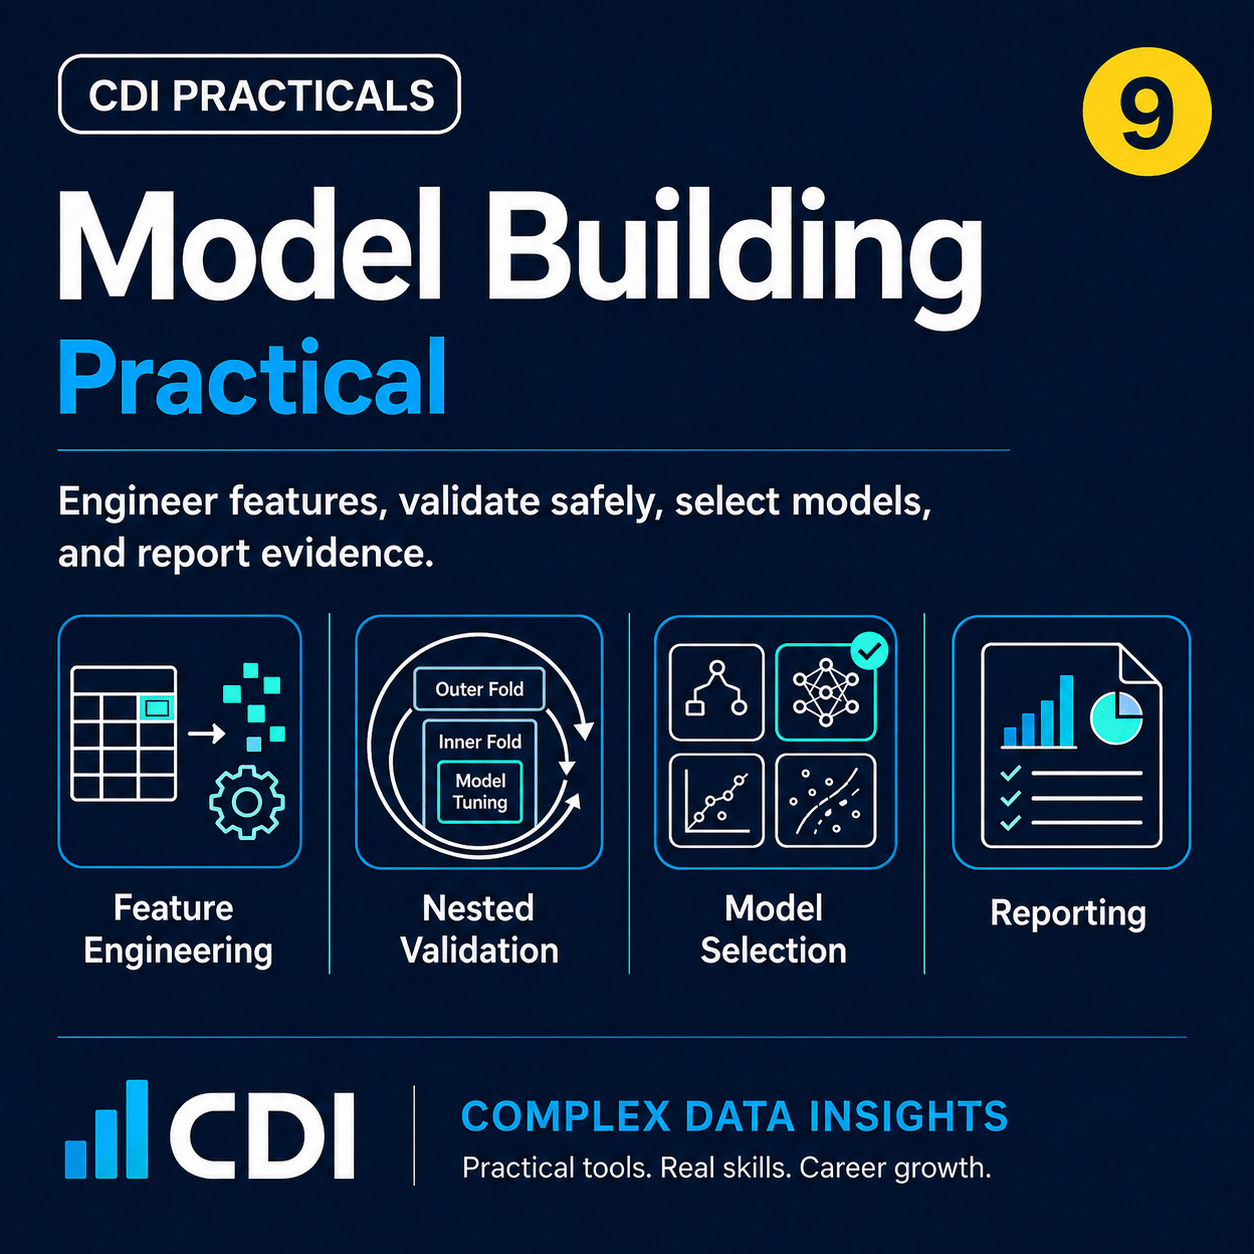
Model Building Practical is a hands-on guide to developing classification models through a rigorous, leakage-safe, and reproducible workflow with Python and scikit-learn.
You will work with cleaned synthetic service-delivery data and progress from defining the model-development brief to purposeful feature engineering, controlled hyperparameter tuning, nested cross-validation, model selection, calibration assessment, holdout evaluation, structured error analysis, and evidence-aware reporting.
The workflow compares regularized logistic regression and random forest pipelines while keeping the final holdout set untouched. A transparent selection rule requires meaningful performance improvement before additional model complexity is accepted.
What You Will Learn
- Define a clear model-development brief, cohort, target, prediction moment, primary metric, and holdout rule.
- Freeze an untouched holdout set before iterative model development.
- Engineer and document domain-informed features without introducing data leakage.
- Build mixed-type preprocessing and candidate pipelines with scikit-learn.
- Design purposeful and interpretable hyperparameter search spaces.
- Use nested cross-validation to separate hyperparameter tuning from performance estimation.
- Assess fold variation, learning curves, probability calibration, Brier score, feature importance, and error patterns.
- Apply a transparent model-selection rule before evaluating the selected specification on the holdout set.
- Interpret permutation importance and model errors without making unsupported causal claims.
- Save, reload, and verify a complete fitted pipeline.
What You Will Produce
- A model-development brief and feature-engineering plan.
- A feature dictionary and base-versus-engineered feature comparison.
- Nested cross-validation and hyperparameter-selection evidence.
- Learning-curve, calibration, confusion-matrix, and permutation-importance figures.
- Holdout performance, prediction, and structured error-analysis tables.
- A model-selection decision log and concise model-building report.
- A verified end-to-end fitted pipeline.
- A reproducibility manifest containing dataset and model checksums.
Included
- Online step-by-step CDI Practical
- Downloadable project files
- Synthetic dataset and reproducible dataset generator
- Complete Python model-building workflow
- Bash workflow scripts
- Reference figures and evidence tables
- Fitted example pipeline and run manifest
- Learner README and requirements file
Who This Practical Is For
This practical is designed for students, researchers, analysts, professionals, mentors, and Python users ready to move beyond introductory model fitting and develop more defensible machine-learning workflows.
Tools: Python, pandas, NumPy, scikit-learn, Matplotlib, seaborn, joblib, and Quarto.
Important: This practical is intended for education, portfolio evidence, and local technical testing. Its synthetic data and fitted demonstration model are not validated for operational, clinical, or other real-world decisions affecting people. They must not be used to rank people, allocate or deny services, or automate consequential decisions.